
Artificial intelligence has evolved into a common part of everyday life, from voice assistants to speech-to-text tools. But when technology struggles to recognize the way Black people of varied regions speak, using these tools becomes another exercise in code-switching. Howard University is working with Google Research to change that by teaching artificial intelligence to better recognize the diversity of African American English.
Through Project Elevate Black Voices, researchers from the historically Black university and Google Research collected 600 hours of audio from speakers across 32 states to develop a dataset that reflects the different dialects, diction and speech patterns found throughout Black communities. The goal is to help automatic speech recognition (ASR) technology, which converts spoken language into text or commands, more accurately understand Black users without requiring them to alter their natural speech — or in other terms, code switch.
The collaboration aims to address these gaps by making the Howard African American English Dataset 1.0 available initially to researchers and institutions within the historically Black college and university (HBCU) network. By prioritizing these institutions, Howard hopes to support research that better reflects the needs of Black communities and encourages more inclusive technological development.
Importantly, Howard University will retain ownership of the dataset and its licensing, serving as a steward of how the information is used. Google Research can also use the data to improve its products. The arrangement gives Howard a central role in determining how this resource is managed while creating opportunities for other HBCUs to conduct research and develop technology that better recognizes African American English.
The project’s community-centered approach also reflects the importance of building trust around how Black people’s voices and data are collected. Researchers organized events featuring local Black panelists who facilitated conversations about culture, artificial intelligence and data privacy before inviting participants to contribute audio recordings.
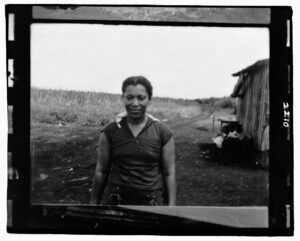
In some ways, the effort resembles the work of Howard alumna Zora Neale Hurston, who earned an Associate’s Degree in English from the university in 1924. A renowned anthropologist and writer, Hurston traveled throughout the American South, Jamaica and the Bahamas, immersing herself in Black communities to document their cultural traditions, storytelling and language. Her commitment to preserving the richness of Black expression is evident in works such as Their Eyes Were Watching God and the short story Sweat, where dialect and dialogue are integral to how her characters communicate their experiences.